Platform Engineering Services
A paved path to production your product teams take because it is the fastest route, with guardrails built into the tooling. Hygge's platform engineering work starts by measuring what a team goes through today to ship one service.
What Platform Engineering Services Build Into a Platform
The parts that decide whether a platform gets adopted or becomes a second thing to work around. Hygge scopes which your teams need after watching them ship.
Service Templates
A new service starts from a working template with logging, health checks, CI, and deployment already wired. The first commit lands in a repository that is already in production shape.
Self-Service Environments
Developers provision what they need through a defined interface, within limits the platform enforces. Internal developer platform work removes the ticket that used to sit between a team and a database.
Golden Paths
One recommended way to do each common thing, documented and supported, so a team choosing the standard route gets the most help.
Guardrails in the Tooling
Standards enforced by the pipeline: security scanning, resource limits, tagging, and access policy. Platform engineering services put the rules inside the pipeline, where every build meets them.
Kubernetes and Runtime
The orchestration layer where the workload justifies it, sized and operated so teams deploy without learning it. Kubernetes consulting covers whether it belongs in your case at all.
Service Catalogue
One place listing what exists, who owns it, and how to call it, so a team finds the service that already solves their problem. An internal developer platform earns most of its adoption here.
What a Developer Experience Audit Settles
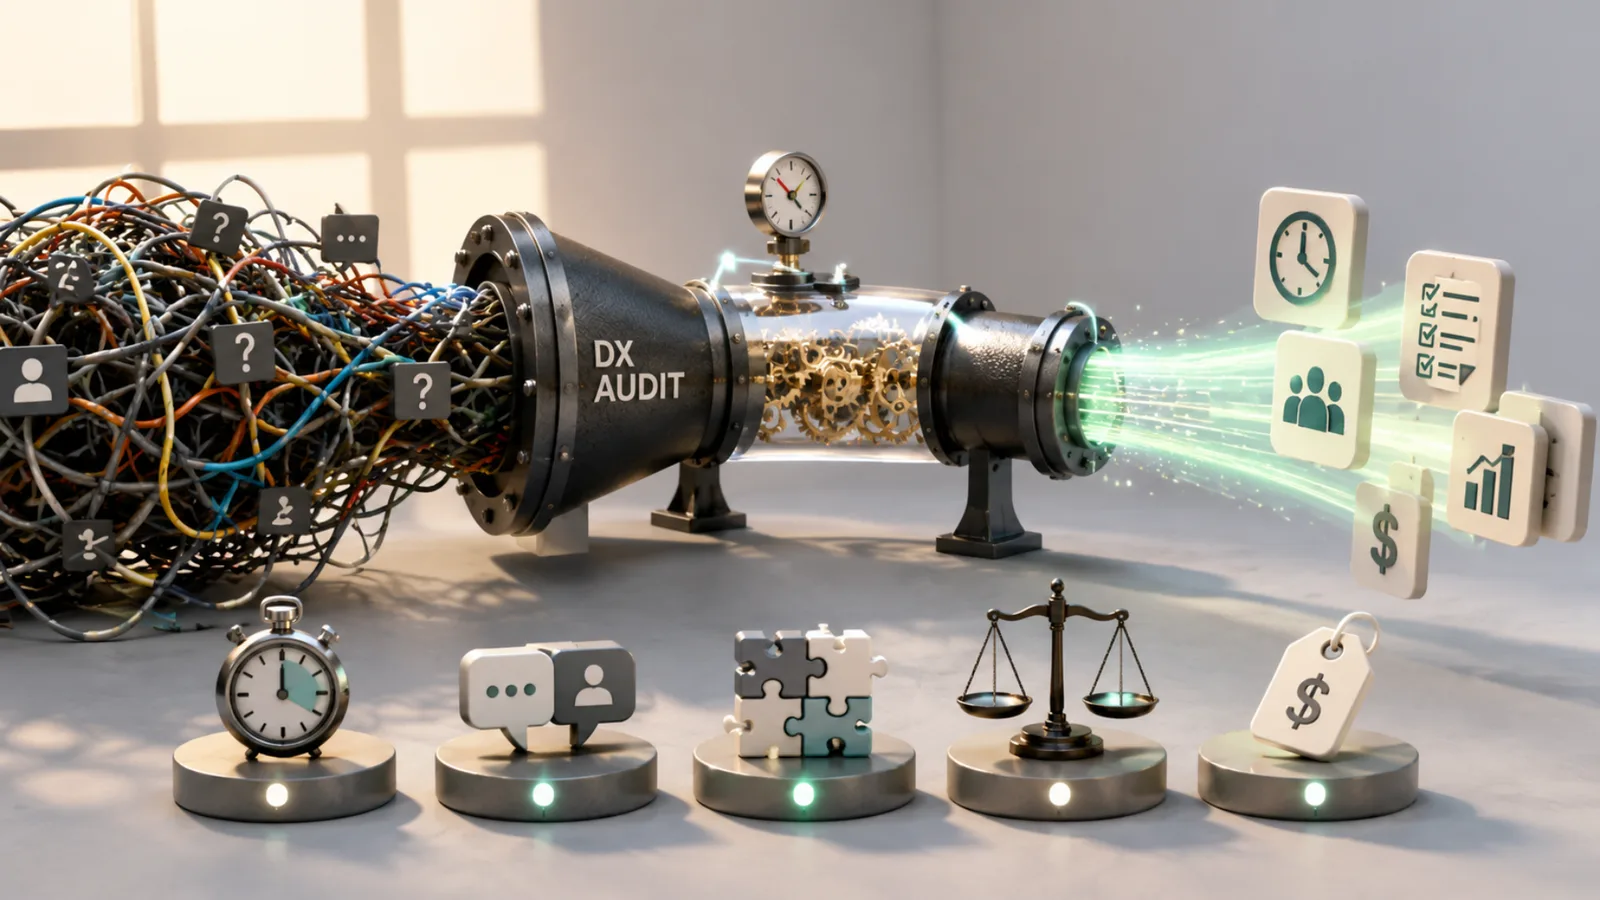
Hygge opens with an audit that follows one team shipping one service end to end. Platform engineering consulting that starts from a reference architecture builds a platform for a company that does not exist.
The audit produces each of these:
- Time from a new repository to a service running in production, measured on a real attempt.
- Every ticket a developer has to file, and who has to answer each one.
- What each team has rebuilt separately because nothing shared existed.
- Whether a platform team is justified at your size, and what it would own.
- Fixed scope and price for phase one, agreed before anything gets built.
What Sends an Organisation to Build a Platform
The situations behind most enquiries Hygge scopes.
Every team solved the same problem their own way, and a new service takes two weeks of setup. Platform engineering gives them one paved path to production. The audit collects what each team built so the platform starts from real use.
Every Team Solved the Same Problem Differently
Four teams, four ways of doing logging, four deployment approaches. Moving an engineer between them costs weeks, and fixing anything centrally means fixing it four times.
A New Service Takes Two Weeks to Stand Up
Most of that is copying configuration from another repository and filing tickets for infrastructure. The actual code takes an afternoon.
Standards Live in a Document Nobody Opens
There is a wiki page describing how things should be done. Compliance depends on whether the reviewer remembers it that day.
The Infrastructure Team Became a Queue
Every environment, database, and permission change waits behind the same three people. They are working hard, and the queue keeps growing.
The Last Platform Nobody Used
A previous internal platform was built without asking the teams, mandated, and quietly routed around. The organisation is wary of a second attempt.
How We Build an Internal Platform
From watching one team ship to a platform other teams choose, with adoption measured at every stage. This is how platform engineering services run at Hygge.
Developer Experience Audit
Three weeks following real teams through real work, ending in a measured baseline, a scope, and an exact price.
Pick the First Pain
The single step costing the most time across teams gets solved first, which is what earns the platform its first users.
Build With a Pilot Team
One team uses the platform while it is being built, so the interface is shaped by people who have to live with it. Kubernetes consulting and runtime choices get tested against that team's real work.
Make It the Fastest Route
Templates, documentation, and support that make the standard path the quickest one, which is what adoption depends on.
Hand the Platform Over
Ownership, runbooks, and a support model for your own platform team, along with the measurements that show whether it is still earning its keep.
What Changes Once the Path Is Paved
A new service ships on day one, on a path the whole company already trusts. Standards stop living in a document nobody opens, because the platform applies them by default. Platform engineering and SRE services overlap in practice: the first builds the path to production, the second decides what happens when it breaks at three in the morning. Kubernetes services sit under both, once the workload justifies the operational cost.
What Platform Engineering Gives Back
Every number here is agreed with you before work starts, then measured against how things run today.
Where Shared Tooling Starts Saving Real Money
Sectors where enough teams ship that each one rebuilding the same pipeline is a visible cost.
Retail & E-Commerce
Retail groups running storefront, fulfillment, and merchandising teams that each deploy on their own schedule.
Media & Entertainment
Media organizations with catalog, playback, and rights teams sharing one delivery estate.
Sales & Marketing Technology
Revenue orgs where several squads integrate against the same CRM and step on each other.
Healthcare & Staffing
Health platforms where every new service inherits the same access and audit requirements.
Logistics & Warehouse Automation
Logistics groups rolling the same software to sites that each have local differences.
EdTech
Education platforms where course, assessment, and reporting teams release independently.
Real Estate & PropTech
Property groups running portal, agency, and consumer products off shared services.
Aviation
Aviation operators where every deployment has to pass the same approval gate.
Platforms Teams Chose to Use
Platform engineering services delivered and handed to internal teams.
Country Navigator
A decade-old monolith serving enterprise customers, rebuilt into services and given a production AI assistant, with the user base migrated without downtime.
- 0Downtime moving a decade-old platform
- 1 configReplaces the SSO setup only one person knew
- 10 yearsOf monolith rebuilt into services
What You Get From the Audit
A measured time from new repository to production, every ticket a developer has to file with its owner, an inventory of what teams rebuilt separately, an answer on whether a platform team is justified at your size, and an exact price for phase one. Platform engineering consulting that starts from your own teams.
Kubernetes Services and the Stack We Build On
Chosen against your workloads, your team size, and what your own platform people will operate.
The layer that schedules workloads, restarts what fails, and gives every team the same deployment target, so a new service inherits a working setup on day one.
 Kubernetes
 Docker
 Helm
 Istio
Frequently Asked Questions
What engineering leaders ask before investing in platform engineering and kubernetes services.
 What does a platform engineer do?
What is the difference between DevOps and platform engineering?
When to use platform engineering?
What is a platform team?
What is platform engineering vs DevOps?
What is platform engineering?
How is it different from DevOps?
When does a team need an internal platform?
Do we need Kubernetes for this?
How long does a platform take to build?
What if teams ignore it?
Who maintains it afterwards?
From Scattered Setups to One Paved Path
Tell us how many teams you have and what it takes them to stand up a service. You get a measured baseline, a first target, and a price, the way every platform engineering services project at Hygge begins.
Tell Us How Many Teams Ship Independently
Share the number of product teams, how each one deploys, and where they keep rebuilding the same thing.
Get a First Consultation
We review your teams, tooling, and deployment paths for anything that would change scope, cost, or timeline.
Receive a Detailed Proposal
A scoped plan with the approach, timeline, and cost, built around your actual team structure.